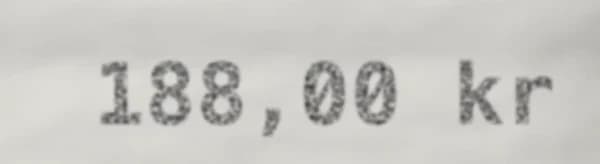Skip to content
DecisionNodeDecisionNde
  • Model
  • Inference
  • Benchmarks
  • Examples
  • Docs
  • Pricing

api all systems normal

Get API keyGet API key
  • dnModelTyped answers, calibrated confidence
  • msInferenceOur own stack and GPUs, answers in ms
  • %BenchmarksAccuracy per suite, with intervals
  • exExamplesBuilds you can start from today
  • /v1DocsQuickstart, API reference, recipes
  • $PricingPay per input token, output is free

decision model + inference api

Typed decisions in milliseconds.

Text, JSON or images in. A choice, a score or a Truth probability out, calibrated, in 5 ms on our own GPUs.

Get API keyGet API keyOpen playground

$0.042 per million input tokens / output is free / no sales call

$0.042 per million input tokens

output is free / no sales call

$0.042 per million input tokens

output is free / no sales call

live

DecisionNode-1.0 Flash

choice
decisionnode-flash-latest

...

“Charged twice and no reply yet.”

Where should this ticket go?

  • billingbilling...
  • bugbug...
  • accountaccount...

auto-refund?acts at 0.80

refundrefund...

confidence...

acts at 0.70deciding

Billing, refund sent

billing + refund

Routed to its queue

otherwise

1,284 actions taken

61 re-checked first

last decisions / on our own GPUsp50 5 ms

  • 09:41:02sort parcelreturns 0.836 ms
  • 09:41:01check chargefraud 0.12 false4 ms
  • 09:40:58moderate postseverity 0.414 ms
New ticketwebhook

one HTTPS call from anything you already run

any http client / POST /v1/decide

any http client / POST /v1/decide

one HTTPS call from anythingyou already runany http client / POST /v1/decide

also go, ruby, curl, webhooks

billing 0.875 ms

  • typescriptts/jsdn.decide()dn.decide()
  • pythonpythondn.decide()dn.decide()
  • gogodn.Decide()dn.Decide()
  • rubyrubydn.decidedn.decide
  • DecisionNode
    /v1/decideDecisionNode
  • curlcurl-X POST-X POST
  • mcpmcptools/calltools/call
  • webhookswebhookson eventon event
  • agentsagentsbefore actingbefore acting
same order, two engines

Sixteen answers before the first word.

The same order and the same sixteen checks. DecisionNode answers them all in one pass while a chat LLM is still writing.

DecisionNode-1.0 Flash0 mscost0.0000¢ready
a chat LLM0 ms0.0000¢ready

$ check-order 48213 --checks 16

one request, two engines

state 3 items, €186.40, Hamburg DE to Lyon FR, gift note, WELCOME40 used 4× this week

truthIs this statement true? One calibrated probability from 0.00 to 1.00 that the statement is true. 0.80 means true about 8 times in 10. Your code picks the cut-off: 0.50 for a plain yes or no, higher when acting on a false yes is costly.

DecisionNode-1.0 Flash

POST /v1/decide, one call

0 mscost0.0000¢
typed answersTtruthCchoiceSscore0 of 16
  • request200 OK16 questions, one callmodel decisionnode-1.0-flash
  • fraud_risktruthTasked0.04 false
  • address_validtruthTasked0.97 true
  • gift_ordertruthTasked0.93 true
  • ship_lanechoiceCaskedstandard 0.88
  • carrierchoiceCaskedcourier 0.81
  • priorityscoreSasked1.8 of 3
  • fragile_itemstruthTasked0.91 true
  • needs_signaturetruthTasked0.22 false
  • customs_formtruthTasked0.03 false
  • promo_abusetruthTasked0.71 true
  • duplicate_ordertruthTasked0.06 false
  • stock_reservedtruthTasked0.99 true
  • packagingchoiceCaskedpadded 0.76
  • delivery_riskscoreSasked0.6 of 4
  • split_shipmenttruthTasked0.12 false
  • next_actionchoiceCaskedship 0.84
  • usagepending410 tokens in, 0 out

> ready

All sixteen answered before the LLM's first word.

> Shipped by courier, padded box. WELCOME40 flagged.

a chat LLM

chat completion, "reply in JSON"

0 mscost0.0000¢
streamed text0 of 16

> ready

ready

> Nothing shipped yet.

Same order, same sixteen checks. Watch both clocks.

136×faster

and counting, the LLM is still writing

time to all 16 answers
25 ms against 3.40 s
cost of this order
0.00086¢ against 0.42¢
price ratio
about 480× cheaper

DecisionNode-⁠1.0 Flash against Claude Sonnet 5.5, the median of the 8 general LLMs on our benchmarks page. Time: DecisionNode-⁠1.0 Flash's 19 ms end-to-end median plus 6 ms for the extra questions; Claude Sonnet 5.5's first token at 630 ms, then 126 output tokens at 22 ms each. Cost is tokens times list price: 410 input tokens at $0.021 per 1M, output free, against 756 input tokens at $3 and 126 output tokens at $15 per 1M. Mock timings. Preliminary results, October 2026.

See every model compared
Race: sixteen checks on one order, DecisionNode-1.0 Flash against a chat LLM
checkDecisionNode-1.0 Flash, typed answera chat LLM, text answer
Is this order fraud? (truth)0.04 false"fraud_risk": "low"
Is the address deliverable? (truth)0.97 true"address_valid": "yes"
Is this a gift? (truth)0.93 true"gift_order": "true"
Which ship lane? (choice)standard 0.88"ship_lane": "standard shipping"
Which carrier? (choice)courier 0.81"carrier": "courier"
How urgent, 0 to 3? (score)1.8 of 3"priority": "medium-high"
Any fragile items? (truth)0.91 true"fragile_items": "yes, the lamp"
Needs a signature? (truth)0.22 false"needs_signature": "probably not"
Needs a customs form? (truth)0.03 false"customs_form": "no"
Is the promo code abused? (truth)0.71 true"promo_abuse": "possibly"
Is this a duplicate order? (truth)0.06 false"duplicate_order": "no"
Is the stock reserved? (truth)0.99 true"stock_reserved": "yes"
Which packaging? (choice)padded 0.76"packaging": "padded box"
Delivery risk, 0 to 4? (score)0.6 of 4"delivery_risk": "low"
Split into two parcels? (truth)0.12 false"split_shipment": "false"
Ship, hold, route or flag? (choice)ship 0.84"next_action": "ship it"
  • time to all 16 answers: 25 ms against 3.40 s
  • cost of this order: 0.00086¢ against 0.42¢
  • price ratio: about 480× cheaper
the decision model

A model built to decide.

Hand-written rules break on the first message nobody planned for. Chat models word the same answer differently every time. DecisionNode returns a typed answer and how sure it is, the same way every time.

How a decision runs

  1. in

    State and questions

    text, JSON or images
  2. call

    One request

    POST /v1/decide
  3. model

    Our model on our GPUs

    one pass, no text generated
  4. out

    Typed answers

    a choice, a score or a truth
  5. branch

    Your code branches

    confidence < 0.70

Four ways to ask

Every type names its answer: choice (one of your labels), score (a level on your scale), truth (a probability), number (a value on your grid). One message, four questions:

state“Customer: I was charged twice and nobody has replied for 3 days.”

Choice "choice", pick one option from your list

question

"route": {
  "type": "choice",
  "criteria": {
    "billing": "money",
    "bug": "broken",
    "account": "login"
  }
}

answer

"route": {
  "type": "choice",
  "choice": "billing",
  "confidence": 0.81,
  "probabilities": {
    "account": 0.05,
    "billing": 0.87,
    "bug": 0.08
  }
}

question

"urgency": {
  "type": "score",
  "criteria": [
    "routine", "today",
    "urgent", "critical"
  ]
}

answer

"urgency": {
  "type": "score",
  "score": 2.31,
  "confidence": 0.47,
  "probabilities": {
    "0": 0.01, "1": 0.09,
    "2": 0.48, "3": 0.42
  }
}

question

"refund": {
  "type": "truth",
  "instructions":
    "Refund this automatically?",
  "criteria": {
    "true":
      "Charged twice for the same order",
    "false":
      "Any other billing issue"
  }
}

answer

"refund": {
  "type": "truth",
  "truth": 0.94
}

question

"days_waiting": {
  "type": "number",
  "instructions":
    "Days without a reply?",
  "min": 0,
  "max": 30
}

answer

"days_waiting": {
  "type": "number",
  "number": 3,
  "expected": 3.06,
  "confidence": 0.88,
  "probabilities": {
    "2": 0.04, "3": 0.88,
    "4": 0.06, "5": 0.02
  }
}
billing0.00
bug0.00
account0.00

picks billing, confidence 0.81

0.000.000.000.00
0routine1today2urgent3critical

score 0.00 of 3, confidence 0.47

0.80010.00falsetrue

One calibrated probability from 0.00 to 1.00 that the statement is true. 0.80 means true about 8 times in 10. Your code picks the cut-off: 0.50 for a plain yes or no, higher when acting on a false yes is costly.: 0.94 true

refunds at 0.80

  1. >truth >= 0.80refund issued
  2. >truth >= 0.50full model re-checks
  3. >elsebilling reply sent

3(0.88)

expected 3.00

grid 0 to 30

0.000.000.000.000.000.000.000.000.00
012345678
030

One value on a grid you set (min, max and an optional step), with a calibrated probability for every value: the most probable value, the expected value and the confidence.: 3, confidence 0.88, expected 3.06

returns choice, probabilities, confidenceTry it in the playground→

0101234567890012345678901

One request answers every question

Send the state once with every question you have. It is read in one pass and shared, so ten questions cost about the same as one.

POST /v1/decidereq_8c41e07breq_8c41e07banswered in 5.7 msanswered in 5.7 ms
  1. stateread once0.0 ms62 tokens
  2. routechoicebilling
  3. urgencyscore2.31 urgent
  4. refundtruth0.94 true
0245.7 ms
zoom,in parallelroute+0.4 msurgency+0.5 msrefund+0.3 ms

62 input tokens, 0 output1 pass, no text generated

02012345678900123456789012

Confidence you can act on

Every answer says how sure the model is, and the numbers are calibrated. Set a line once: above it your code acts instantly. Below it, the full model checks the same request again, or your code takes the safe path. Nobody waits.

ticket 4471routeact at
  1. DecisionNode-1.0 Flashbilling, 4.8 ms0.58below line
  2. re-checkDecisionNode-1.0billing, +8.1 ms0.91above line
  3. actedmoved to billing, reply sent12.9 ms

>if (flash.confidence >= 0.70) act()>else if (full.confidence >= 0.70) act()>else safePath()

030123456789001234567890123

Text and images in one call

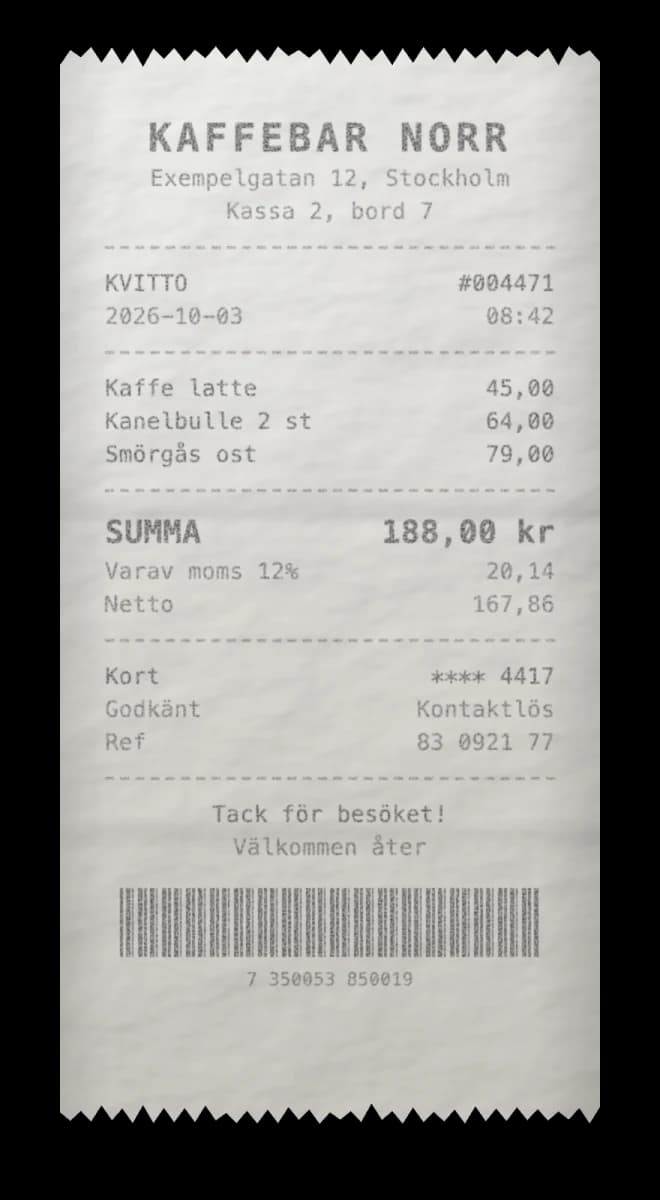
Attach a photo to the same request. The model reads printed text, amounts and layout, and answers with the same question types.

which currency is on this receipt?choice, image + text
Photo of a till receipt from Kaffebar Norr in Stockholm, total 188,00 kr with 12% moms

read from 188,00 kr

reading the receipt…

0.000.000.000.000.000.00
  • SEKSEK
  • NOK
  • DKK
  • EUR
  • USD
  • GBP

answer SEK, read from 188,00 krconfidence 0.83

[ a model company and an inference company ][ model company, inference company ]

We build the decision modeland the machine it runs on.

one tick, one decision

now

  • 09:00
  • 11:00
  • 13:00
  • 15:00
  • 17:00
  • 19:00
inference

Fast because we own the path.

Our own decision model on our own inference stack and GPUs. No third-party API between your request and the answer.

Every hop is ours

One pass, no text generation, nothing in between. DecisionNode-⁠1.0 Flash answers a short request in about 5 ms.

the path of one request

  1. { }requestyour app
  2. 1×read oncetext, images
  3. ?questionsat once
  4. routebilling 0.875 msdecideour stack

no sampling: same answer every time

One fleet, two models

Both models run on our own GPUs behind one API. Switch with the model field; nothing else changes.

share of traffic, last hour

  • DecisionNode-1.0

    decisionnode-latest

    p50
    9 ms
    per 1M in
    $0.042
    share
    61%0%
  • DecisionNode-1.0 Flash

    decisionnode-flash-latest

    p50
    5 ms
    per 1M in
    $0.021
    share
    39%0%

same request, same answer

Done before an LLM writes a word

A chat LLM writes its answer token by token and needs half a second to four seconds. DecisionNode reads the input once and answers in one pass, fast enough for every request, every payment, every robot frame.

End to end from one client, network included, one short decision. The chat LLM band spans 8 general LLMs on the same decision. Preliminary results, October 2026.

time to a typed answer, end to end, log scale

1 ms28× to 214× faster on Flash

  • DecisionNode-1.0 Flash

    5 ms on our side

    routebilling 0.8719 ms
  • DecisionNode-1.0

    9 ms on our side

    refund0.94 true24 ms
  • a chat LLM

    8 LLMs 540 to 4,060 ms

    1,290 ms
1 ms101001,000 ms

End to end from one client, network included, one short decision. The chat LLM band spans 8 general LLMs on the same decision. Preliminary results, October 2026.

Time to a short typed answer, end to end from one client, on a log scale: DecisionNode-1.0 Flash 19 ms, DecisionNode-1.0 24 ms, general LLMs 540 to 4,060 ms.
modeltime to answernote
DecisionNode-1.0 Flash19 ms5 ms on our side
DecisionNode-1.024 ms9 ms on our side
a chat LLM1,290 ms8 general LLMs, 540 to 4,060 ms

28× to 214× faster on Flash

Paste your own request and watch the clock.

How we measured→Open playground
sessionscomingcoming soon

A decision for every frame.

Open one session, send the fixed part once, then stream frames over a WebSocket. Every frame comes back as a typed decision, a decision layer that feeds your controller.

POST /v1/sessionscomingcoming soonsession opening

sent once instructions, mission brief, geofence, 2 questions, window 8, model decisionnode-latest

each frame bills only its own tokens

Survey drone, line inspection

/v1/sessions/ses_7f3a/stream

frames in0

geofenceHhome
mission mapwind3.0 m/s
battery66%to home0 m
opening

frametelemetry JSON; text and images work too


window 8←leaves context

contextsent once

Typed decisions

decisions out0

waiting for the first frame

modechoiceWhich flight mode now?

  • continue...
  • hold...
  • return...
  • land...

confidence ... 

aborttruthShould the mission be aborted now?

...

0aborts at 0.801

Your flight controller 

flies the drone and reads each decision

  1. >controller.set_mode(mode.choice)
  2. >if abort.truth >= 0.80: controller.land()

replies

    More than 10 decisions a second? Use a session.

    Same models, same typed and calibrated answers, the same safety check on every frame. The context is billed once when the session opens; each frame, its own tokens.

    Read the sessions docs
    A survey drone streams telemetry frames into one session; every frame is answered with a flight mode and an abort probability
    frametelemetrymode: Which flight mode now?abort: Should the mission be aborted now?
    1battery 0.64, wind 4.2 m/s, 155 m from homecontinue 0.93, confidence 0.91 (continue 0.93, hold 0.04, return 0.02, land 0.01)0.02 false
    2battery 0.63, wind 4.6 m/s, 225 m from homecontinue 0.93, confidence 0.91 (continue 0.93, hold 0.04, return 0.02, land 0.01)0.02 false
    3battery 0.61, wind 5.1 m/s, 295 m from homecontinue 0.92, confidence 0.89 (continue 0.92, hold 0.05, return 0.02, land 0.01)0.02 false
    4battery 0.60, wind 5.8 m/s, 365 m from homecontinue 0.91, confidence 0.88 (continue 0.91, hold 0.05, return 0.03, land 0.01)0.03 false
    5battery 0.58, wind 6.6 m/s, 435 m from homecontinue 0.88, confidence 0.84 (continue 0.88, hold 0.07, return 0.04, land 0.01)0.03 false
    6battery 0.56, wind 8.9 m/s, 500 m from homecontinue 0.71, confidence 0.61 (continue 0.71, hold 0.22, return 0.06, land 0.01)0.06 false
    7battery 0.54, wind 11.8 m/s, 530 m from homehold 0.62, confidence 0.49 (continue 0.27, hold 0.62, return 0.09, land 0.02)0.14 false
    8battery 0.52, wind 12.6 m/s, 535 m from homehold 0.71, confidence 0.61 (continue 0.19, hold 0.71, return 0.08, land 0.02)0.17 false
    9battery 0.51, wind 12.2 m/s, 535 m from homelatest wins: skipped, a newer frame came in
    10battery 0.50, wind 11.4 m/s, 540 m from homelatest wins: skipped, a newer frame came in
    11battery 0.48, wind 9.6 m/s, 565 m from homecontinue 0.58, confidence 0.44 (continue 0.58, hold 0.33, return 0.07, land 0.02)0.09 false
    12battery 0.45, wind 9.2 m/s, 635 m from homecontinue 0.69, confidence 0.59 (continue 0.69, hold 0.23, return 0.06, land 0.02)0.06 false
    13battery 0.42, wind 10.1 m/s, 705 m from homecontinue 0.62, confidence 0.49 (continue 0.62, hold 0.21, return 0.15, land 0.02)0.06 false
    14battery 0.39, wind 10.6 m/s, 770 m from homecontinue 0.44, confidence 0.25 (continue 0.44, hold 0.17, return 0.37, land 0.02)0.07 false
    15battery 0.36, wind 11.0 m/s, 835 m from homereturn 0.52, confidence 0.36 (continue 0.31, hold 0.14, return 0.52, land 0.03)0.08 false
    16battery 0.34, wind 11.2 m/s, 830 m from homereturn 0.71, confidence 0.61 (continue 0.17, hold 0.09, return 0.71, land 0.03)0.08 false
    17battery 0.31, wind 11.4 m/s, 820 m from homereturn 0.84, confidence 0.79 (continue 0.09, hold 0.05, return 0.84, land 0.02)0.07 false
    18battery 0.29, wind 11.9 m/s, 750 m from homereturn 0.88, confidence 0.84 (continue 0.06, hold 0.04, return 0.88, land 0.02)0.06 false
    19battery 0.27, wind 12.3 m/s, 670 m from homereturn 0.90, confidence 0.87 (continue 0.05, hold 0.03, return 0.90, land 0.02)0.06 false
    20battery 0.25, wind 12.8 m/s, 585 m from homereturn 0.91, confidence 0.88 (continue 0.04, hold 0.03, return 0.91, land 0.02)0.06 false
    console

    Your decisions, live.

    The console every workspace gets, shown with sample data: volume, confidence, latency and every action your software took on its own.

    decisions per hour, last 7 days

    1.1k17.4k / hrnow
    • 00
    • 06
    • 12
    • 18
    • wedwed
    • thuthu
    • frifri
    • satsat
    • sunsun
    • monmon
    • tuetue
    decisions per hour, last 7 days, per hour
    hourswedthufrisatsunmontue
    00 to 032.3k2.5k2.4k2.0k1.8k2.6k2.7k
    03 to 061.5k1.7k1.6k1.3k1.1k1.8k1.9k
    06 to 094.0k4.3k3.9k2.3k2.0k4.4k4.6k
    09 to 1211.2k12.1k11.0k4.8k4.2k12.6k13.0k
    12 to 1515.6k16.4k14.8k6.3k5.7k17.1k17.4k
    15 to 1814.1k15.2k13.0k6.0k5.5k15.8klater today
    18 to 218.8k9.6k8.1k4.6k4.3k10.0klater today
    21 to 244.5k4.9k4.6k3.1k2.9k5.1klater today

    acted on at once

    0%Share of decisions acted on at once this hour: 84%

    of decisions cleared the 0.70 threshold

    actions taken, live

      27842,784 re-checked by DecisionNode this hour

      confidence over the week

      0.51.0threshold 0.700.920.55
      1. wed
      2. thu
      3. fri
      4. sat
      5. sun
      6. mon
      7. tue
      • acted on at onceat once
      • re-checked firstre-checked
      Average confidence per day: answers acted on at once stay near 0.92, answers re-checked by DecisionNode came in near 0.55, under the 0.70 threshold. Use the arrow keys to read each day.
      dayacted on at oncere-checked first
      wed0.900.52
      thu0.920.56
      fri0.890.49
      sat0.930.58
      sun0.940.61
      mon0.910.54
      tue0.920.55

      server latency, last hour

      p50 7 msp99 21 ms
      24%
      06121824 ms

      Request in to answer out, both models.

      Histogram of server latency over the last hour, both models: p50 7 milliseconds, p99 21 milliseconds.
      msof requests
      0 to 21%
      2 to 49%
      4 to 624%
      6 to 822%
      8 to 1015%
      10 to 1210%
      12 to 147%
      14 to 165%
      16 to 183%
      18 to 202%
      20 to 221%
      22 to 241%

      Every workspace gets this console from its first request.

      Open the console→Get API keyGet API key
      benchmarks

      How accurate it is, measured.

      15 suites of real decisions, from policy rules to web tasks and prompt injection. Every system answered the same items.

      15-suite mean

      Mean accuracy over every text suite, one dot per system.

      25,134 items

      Preliminary results, October 2026

      0.550.600.650.700.750.800.85
      1. 3Cloudflare Clef 27B0.778 to 0.7940.7860.786, 95% interval 0.778 to 0.794
      2. 5Cloudflare Clef-flash 9B0.750 to 0.7670.7590.759, 95% interval 0.750 to 0.767
      3. 7Cygnet (Gemma 4 12B)0.710 to 0.7260.7180.718, 95% interval 0.710 to 0.726
      4. 1DecisionNode-1.0ours0.809 to 0.8250.8170.817, 95% interval 0.809 to 0.825
      5. 4DecisionNode-1.0 Flashours0.771 to 0.7890.7800.780, 95% interval 0.771 to 0.789
      6. 2TypeSafe Jev 1.13, note 10.795 to 0.8110.8030.803, 95% interval 0.795 to 0.811
      7. 8Kev-4B0.708 to 0.7260.7170.717, 95% interval 0.708 to 0.726
      8. 6pplx-decider-27b0.738 to 0.7550.7460.746, 95% interval 0.738 to 0.755
      9. 9Strands Decider 2B, note 20.612 to 0.6300.6210.621, 95% interval 0.612 to 0.630

      accuracy, the line across each dot is its 95% interval

      1. 1Note 1, TypeSafe Jev 1.13: called through its official API. Reads text only, so it has no image results.
      2. 2Note 2, Strands Decider 2B: its published training data contains items of two of our test sets.

      where we lead

      Pick a suite to rank every system.

      0.500.751.00

      where we trail

      0.500.751.00

      DecisionNode-1.0Jevline length is the gap in points

      flash, end to end

      19 ms

      5 ms of it on our side

      Flash8 general LLMs1 ms10 ms100 ms1 s10 s

      DecisionNode-⁠1.0 Flash answers in 19 ms end to end, 5 ms of it on our side. 8 general LLMs took 540 to 4060 ms on the same decision, timed from the same client.

      28× to 214× faster than 8 general LLMs on the same decision, timed from one client. A speed comparison against other decision APIs comes at launch.

      against general llms

      Eight general LLMs, the same 2,000 decisions.

      Asked for JSON, a chat model sometimes returns something your code cannot use, or routes the same ticket two ways. DecisionNode returns the shape you asked for, the same way, every time.

      • ours
      • OpenAI
      • Anthropic
      • Google
      • tap or hover a dot
      Compare with general LLMs

      Preliminary results, October 2026

      invalid answers

      0.00%

      DecisionNode-1.0 and Flash

      0%4%

      general LLMs0.30% to 3.85%

      • Claude Fable 5.1: 0.30%
      • Claude Opus 5.5: 0.45%
      • GPT-5.6 Sol: 0.60%
      • Claude Sonnet 5.5: 0.90%
      • Gemini 3.1 Pro: 1.10%
      • GPT-5.6 Terra: 1.45%
      • Gemini 3.8 Flash: 2.40%
      • GPT-5.6 Luna: 3.85%

      same answer twice

      100%

      DecisionNode-1.0 and Flash

      100%90%

      general LLMs91.4% to 97.3%

      • Claude Fable 5.1: 97.3%
      • Claude Opus 5.5: 96.6%
      • GPT-5.6 Sol: 96.1%
      • Claude Sonnet 5.5: 95.2%
      • Gemini 3.1 Pro: 95.0%
      • GPT-5.6 Terra: 94.5%
      • Gemini 3.8 Flash: 92.8%
      • GPT-5.6 Luna: 91.4%

      per 1,000 decisions

      $0.0038

      DecisionNode-1.0 Flash

      $0.001$100

      general LLMs$0.057 to $33.30

      • GPT-5.6 Luna: $0.057
      • Gemini 3.8 Flash: $0.23
      • GPT-5.6 Terra: $0.46
      • Claude Sonnet 5.5: $1.89
      • Gemini 3.1 Pro: $4.44
      • GPT-5.6 Sol: $8.50
      • Claude Opus 5.5: $9.10
      • Claude Fable 5.1: $33.30

      2,000 requests per system, LLMs prompted for the JSON shape, list prices, October 2026.

      15 text suites, 25,134 items. Accuracy with 95% intervals by a paired bootstrap. Jev was called through its official API; open models ran on our GPUs as their authors serve them. October 2026.

      DecisionNode is not affiliated with TypeSafe AI, Cloudflare, OpenAI, Anthropic, Google or the other model publishers. Their names identify the systems measured.

      See every suite
      pricing

      You pay for input, not for output.

      Answers generate no text, so output costs nothing. Pay per million input tokens from a prepaid balance. No seats, no minimums.

      estimate

      1B tokens

      10M100M1B10B

      about 2,000,000 requests at 500 input tokens each

      DecisionNode-1.0, a month

      $42.00$​0123456789 40123456789 20123456789 .00123456789 00123456789 0.,

      Flash, a month

      $21.00$​0123456789 20123456789 10123456789 .00123456789 00123456789 0.,

      output tokens$0.00

      batch jobshalf price

      Get API keyGet API key
      • DecisionNode-1.0 Flash

        $0.021

        per 1M input tokens

        batch jobs $0.0105, multi-hour delay

        decisionnode-flash-latest

        • our fastest tier, about 5 ms
        • half the price per token
        • the same answer shapes
        • one field to switch models
        Get API keyGet API key
        Get API keyGet API key
      • DecisionNode-1.0

        full model

        $0.042

        per 1M input tokens

        batch jobs $0.021, multi-hour delay

        decisionnode-latest

        • our most accurate model
        • best on subtle calls
        • reads small print in images
        • the playground default
        Get API keyGet API key
        Get API keyGet API key
      • Dedicated

        Custom

        capacity reserved for you

        both models

        • capacity on our own GPUs
        • custom rate limits
        • same API, no code changes
        • a direct line to our engineers
        Talk to usTalk to us
        Talk to usTalk to us

      both models

      • text and images in one request
      • up to 64k tokens of context
      • output always free
      • one API
      faq

      Questions developers ask.

      The short answers. The docs have the long ones, with the request and response for every case.

      Read the docs
      • A chat model writes its answer token by token, so a short answer takes half a second to several seconds and rarely answers the same way twice. DecisionNode reads your input once and answers your typed questions in one pass: a choice, a score or a Truth probability, each with how sure the model is. It generates no text, so it answers in milliseconds.

      • Every type names its answer: choice (one of your labels), score (a level on your scale), truth (a probability), number (a value on your grid). Choice picks one option from the list you send and returns a probability for each. Score places the input on your ordered scale, for example routine to critical, and returns the expected level. Truth (truth in the API) asks whether a statement is true: DecisionNode returns one calibrated probability from 0.00 to 1.00 that it is, so 0.80 means true about 8 times in 10. Your code picks the cut-off: 0.50 for a plain yes or no, higher when acting on a false yes is costly. Number (number in the API) asks: How many, or what value? One value on a grid you set (min, max and an optional step), with a calibrated probability for every value: the most probable value, the expected value and the confidence. A count of cars in a photo, overdue invoices in a statement, a year, a rating out of ten.

      • You pay per million input tokens from a prepaid balance: $0.042 on DecisionNode-⁠1.0, $0.021 on DecisionNode-⁠1.0 Flash. The model writes no text, so every response reports output_tokens: 0 and output never costs anything. No seats, no minimums.

      • DecisionNode-⁠1.0 Flash when speed and volume come first: about 5 ms on a short request, at $0.021 per million input tokens. DecisionNode-⁠1.0 for the hard calls, where accuracy matters most. Many builds run both: Flash first, and any answer under your confidence threshold is re-checked on DecisionNode-⁠1.0 before your code acts.

      • Yes. Send images next to your text in the same request. The model reads printed and handwritten text, amounts, dates, objects and layout, and answers through the same question types.

      • More than 10 decisions a second? Use a session. It is built for loops: survey, inspection and delivery drones, simulators and games, machine monitoring, long-running agents. You open it once with the instructions, the fixed state and the questions, then stream frames (text, JSON or an image) over one WebSocket and get a typed decision back for each frame. Your context stays loaded for the whole session, so each frame costs only its own tokens, and a client that falls behind gets the newest frame answered, never a backlog, with the skipped frames reported. A session is a decision layer that feeds your controller: the vehicle's own control loop keeps flying it.

        • Read the sessions docs
      • Yes. The same request to the same model version returns the same answer, every time. There is no sampling, so your tests hold and every logged decision can be replayed.

      • Get an API key, paste one curl and branch on the typed answer. The quickstart takes under five minutes, and the playground runs any request in your browser first.

        • Get API key
        • Open playground
        • Quickstart
      • Requests are processed to return your answers and to run the service. We do not train our models on your data without your written consent. Inputs and answers are deleted 30 days after each request by default, and zero retention is available on request. The Privacy Policy and the Data Processing Addendum have the details; questions go to privacy@bynn.com.

        • Privacy Policy
        • Data processing
      DecisionNodeDecisionNde

      The decision model, and the inference API that serves it.

      one endpoint: POST api.decisionnode.com/v1/decidePOST /v1/decide

      start building

      Your first decision in minutes.

      Make a key, paste one curl, branch on a typed answer. Prepaid, no sales call.

      • api all systems normalapi normal
      • output is always freeoutput always free
      • same request, same answersame request, same answer

      DecisionNode is built and run by Bynn Intelligence, Inc.

      We train the model and serve it on our own GPUs.

      hello@bynn.com

      product

      • Model
      • Inference
      • Benchmarks
      • Pricing

      developers

      • Docs
      • Quickstart
      • Examples
      • Playground
      • Console

      company

      • Contact
      • Security
      • Report abuse
      • Dedicated

      legal

      • Terms
      • Acceptable use
      • Privacy
      • Data processing
      • Defence addendum
      • Cookies

      © 2026 Bynn Intelligence, Inc.

      prices in USD per 1M input tokens